

There’s a research line on editing facts directly into a model’s weights: ROME, MEMIT, GRACE, WISE. It’s clever, it’s real, and it’s almost always the wrong tool for keeping an enterprise system current. Here’s why, and what to do instead.
The problem
Your model believes something that’s now false. The CEO changed, the fee schedule updated, a product was discontinued. And the model, trained months ago, keeps stating the old fact with full confidence. The tempting question, and one I get asked in client conversations more than almost any other, is: can’t we just edit the model so it knows the new fact? No retraining, no retrieval plumbing, just reach into the weights and change the one thing that’s wrong.
The answer is yes, technically, there’s a whole research field that does exactly this. And no, you almost certainly shouldn’t. This is the one article in the series that’s mostly a warning, because the gap between how good knowledge editing looks in a paper and how it behaves in production is the widest in the knowledge layer: the part of an agent system that decides reliability in production, and an engineering discipline in its own right. Understanding why the obvious-sounding fix is a trap is worth more than the fix would have been.
How knowledge editing works
The spine: locate where in the network a specific fact is stored, and surgically modify those weights to change it, without retraining the whole model.
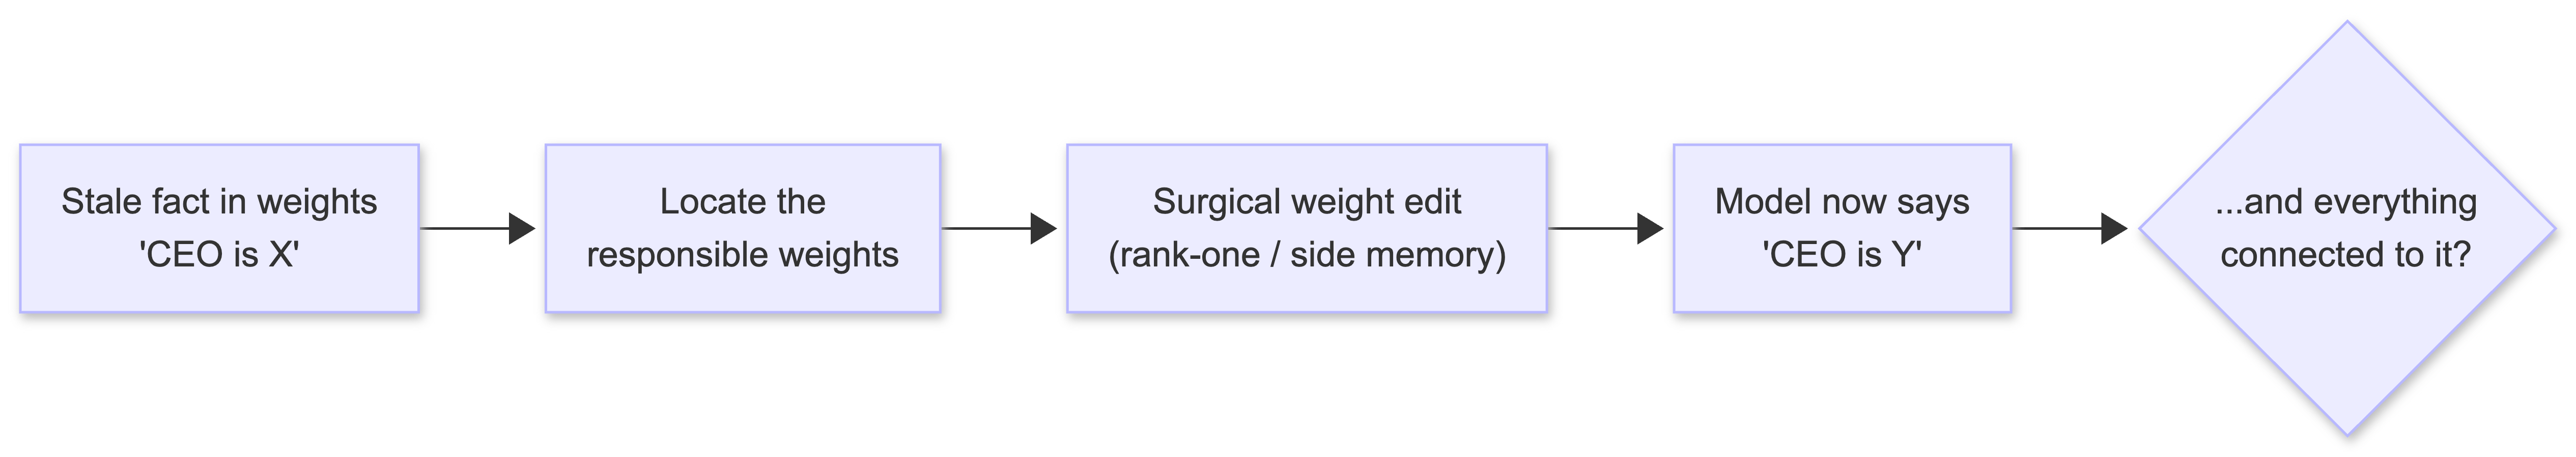
The foundational method is ROME (Kevin Meng and co-authors, Locating and Editing Factual Associations in GPT, [arXiv 2202.05262](https://arxiv.org/abs/2202.05262), NeurIPS 2022), which treats a feed-forward layer as a key-value store and applies a rank-one update to change one association. MEMIT (Meng and co-authors, Mass-Editing Memory in a Transformer, [arXiv 2210.07229](https://arxiv.org/abs/2210.07229), ICLR 2023) scaled the same idea to thousands of edits at once. Two later methods avoid touching the original weights at all: GRACE (Thomas Hartvigsen and co-authors, Aging with GRACE, [arXiv 2211.11031](https://arxiv.org/abs/2211.11031), NeurIPS 2023) writes new facts into a discrete key-value adapter, and WISE (Peng Wang and co-authors, WISE: Rethinking the Knowledge Memory for Lifelong Model Editing of Large Language Models, [arXiv 2405.14768](https://arxiv.org/abs/2405.14768), NeurIPS 2024) keeps a separate “side memory” with a router that decides when to use it.
The arc kept going. AlphaEdit (Junfeng Fang and co-authors, AlphaEdit: Null-Space Constrained Knowledge Editing for Language Models, [arXiv 2410.02355](https://arxiv.org/abs/2410.02355), ICLR 2025 oral) projects each edit onto the null space of the knowledge you want preserved, so an update is mathematically constrained not to disturb what the model already knew. By 2026 that was being patched in turn: AlphaEdit+ (Qing Liu and co-authors, AlphaEdit+: Model Editing in the Presence of Conflicting and Inconsistent Knowledge, [Findings of ACL 2026](https://aclanthology.org/2026.findings-acl.728/)) relaxes those same null-space constraints because they hold up badly once incoming edits conflict with each other, and LightEdit (Dahyun Jung and co-authors, Towards Scalable Lifelong Knowledge Editing with Selective Knowledge Suppression, [ACL 2026](https://aclanthology.org/2026.acl-long.145/)) goes at the same sequential-editing problem from the decoding side, suppressing the original knowledge’s probabilities instead of overwriting the weights that carry it. The progression across these methods is itself a tell: each generation is largely a response to the previous one’s collateral damage, which is the field quietly admitting how hard the side effects are to contain.
In practice: why it fails the enterprise
Here’s the move that looks great in a paper and falls apart in production. Edit a model so “the CEO of Acme is now Y.” The benchmark checks that the model answers the CEO question correctly, and it does. Then a user asks “who does the head of Acme report to,” or “what’s changed at Acme this year,” or the same fact in another language, and the edit doesn’t carry. The model knows the new CEO in exactly the phrasing you tested and nowhere else.
This is the ripple-effects problem, and it’s well-documented. Roi Cohen and co-authors (*Evaluating the Ripple Effects of Knowledge Editing in Language Models*, [arXiv 2307.12976](https://arxiv.org/abs/2307.12976), TACL 2024) built a benchmark specifically for it and showed editing methods fail to propagate a change to the facts logically entailed by it. Worse, the edits don’t stay cheap: Wanli Yang and co-authors (*The Butterfly Effect of Model Editing*, [arXiv 2402.09656](https://arxiv.org/abs/2402.09656), Findings of ACL 2024) showed that even a single edit can trigger model collapse, with significant performance degradation across benchmark tasks, and that nearly every editing method they examined collapsed the model after only a few sequential edits. And the gap between benchmark and reality is stark: a 2025 re-evaluation, The Mirage of Model Editing (Yang and co-authors, [arXiv 2502.11177](https://arxiv.org/abs/2502.11177), ACL 2025), reported the same methods scoring 96.8% under the field’s standard evaluation practice and 38.5% on QAEdit, its realistic question-answering benchmark, the kind of benchmark-to-production cliff that should make any buyer nervous.
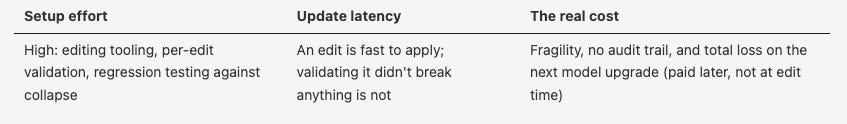
Stack up what that means for an enterprise. Edits are fragile: they hold for the tested phrasing and leak everywhere else. They’re hard to audit: “which facts has this model been edited to believe, and by whom” has no clean answer when the change is diffused into weight matrices, which is a compliance non-starter in a regulated shop. They’re model-specific and perishable: an edit is tied to one model’s exact weights, so the next model upgrade wipes every edit and you start over. And they risk the rest of the model: unlike a corpus change, a weight edit can quietly damage unrelated capabilities. For a system whose entire job is to be reliably current, that’s four strikes.
Where it shines
To be fair, because the methods are genuinely clever and the research matters: knowledge editing has real niches. Research on how facts are stored in transformers is valuable in its own right: ROME’s locating technique taught the field something true about where knowledge lives, independent of whether you ever edit anything. And there are narrow, controlled settings (removing a specific memorized piece of toxic or private content from a model you’re shipping as static weights, where you can’t or won’t run retrieval) where a targeted edit is a reasonable tool. The common thread is that these are static-model problems, not keep-the-knowledge-current problems. Editing is a scalpel for the model artifact, not a mechanism for an evolving enterprise knowledge base.
Where it breaks
The failure modes are the four strikes above, sharpened: fragility under paraphrase and entailment (the ripple-effects result), cumulative model damage under sequential edits (the collapse result), the audit and provenance gap, and the model-version cliff that makes every edit a sunk cost. There’s also an emerging safety angle (once weight-editing is cheap and stealthy, it becomes a tampering vector for a model you receive from someone else), but for the enterprise-currency question, the disqualifier is simpler: editing optimizes for changing a fact, and an enterprise needs to change a fact and prove it, audit it, and keep it across model upgrades. Editing gives you the first and none of the rest.
When not to use it
For keeping an enterprise system’s knowledge current (fee schedules, org charts, product catalogs, policies, anything that changes), don’t use knowledge editing. That’s not a hedge; it’s the recommendation. The alternative is the entire rest of this series: put the changing facts in a retrieval corpus or a knowledge graph and update that. Re-indexing a document is fast, auditable, reversible, and survives a model upgrade untouched, because the knowledge lives outside the model where you can see it and govern it. The instinct to “just fix the model” is the instinct to put mutable state in the most expensive, least observable place you have.
Cost / latency / setup effort:
Combinations and hybrids
There isn’t a satisfying hybrid here, and that’s the honest answer. The closest reasonable pattern is to keep the model static and put all mutable knowledge in the retrieval and memory layers from the earlier articles. That’s less a hybrid than a clean division of labour: the model supplies language and reasoning, the knowledge layer supplies current facts, and the two stay separate precisely so you can update one without disturbing the other. If you find yourself wanting to edit the model to fix a fact, that’s usually a signal your retrieval layer has a gap: the fact should have been retrievable and wasn’t. Fix the corpus, not the weights. The next article is about how you’d know whether any of this is actually working: evaluation.
Production checklist
Default to updating the corpus, not the model: make “edit the weights” a decision that has to be argued for, not the reflex.
If you must edit, test ripple effects, not just the target fact: query the entailed facts, paraphrases, and other languages before trusting it.
Run a regression suite after any edit to catch the collapse the editing benchmarks miss; one edit can degrade unrelated capabilities.
Track every edit as provenance (what, when, who, why), because the weights won’t tell you later.
Assume edits don’t survive a model upgrade and budget to redo or, better, retire them in favour of retrieval.
Treat a wish to edit as a retrieval-gap signal: investigate why the corrected fact wasn’t retrievable first.
The take
Knowledge editing is good research and a bad answer to the enterprise question everyone actually has. Editing a fact into the weights is fragile under paraphrase, opaque to audit, dangerous to the rest of the model, and gone the moment you upgrade. The alternative, updating a retrieval corpus you can see and govern, is faster and safer on every axis that matters in production. Keep the knowledge outside the model where you can change it, prove it, and carry it forward. The urge to reach into the weights is almost always a retrieval gap in disguise.
I take on a small number of advisory engagements each year for teams hitting exactly these problems. Reach out if that’s you.
What to read next
This series:
Article 1 — Your agent’s problem isn’t the model, it’s the knowledge layer
Article 2 — Naive RAG: the baseline you’ll always benchmark against
Article 3 — Advanced RAG: what you actually run in production
Article 4 — GraphRAG and friends: when entities and relationships beat similarity
Article 5 — Agentic RAG: when retrieval becomes a decision, not a pipeline
Article 6 — Vector vs graph vs episodic: a tour of agent memory systems
Article 7 — Context engineering: the discipline that replaces prompt engineering
Article 8 — Knowledge editing and why it isn’t the answer for enterprise updates
Article 9 — Evaluation: how do you know any of this is working? (coming soon)
External:
Meng et al. (NeurIPS 2022), Locating and Editing Factual Associations in GPT (ROME). https://arxiv.org/abs/2202.05262. The foundational method and the locating technique worth knowing.
Cohen et al. (TACL 2024), Evaluating the Ripple Effects of Knowledge Editing in Language Models. https://arxiv.org/abs/2307.12976. The benchmark showing edits don’t propagate to entailed facts.
Yang et al. (Findings of ACL 2024), The Butterfly Effect of Model Editing: Few Edits Can Trigger Large Language Models Collapse. https://arxiv.org/abs/2402.09656. A single edit can trigger collapse, and a few sequential edits reliably do.
Yang et al. (ACL 2025), The Mirage of Model Editing: Revisiting Evaluation in the Wild. https://arxiv.org/abs/2502.11177. The recent benchmark-to-reality gap, and the strongest reason to be skeptical.
Jung et al. (ACL 2026), Towards Scalable Lifelong Knowledge Editing with Selective Knowledge Suppression. https://aclanthology.org/2026.acl-long.145/. Where the sequential-editing problem stands in 2026, and how much machinery it still takes.
Repo: zjunlp/EasyEdit. https://github.com/zjunlp/EasyEdit. One interface over ROME, MEMIT, GRACE, WISE and AlphaEdit, if you want to try the thing yourself before ruling it out.